Cost Optimization Strategies
Minimize evaluation costs while maintaining accuracy.
The Scenario
You're fact-checking news articles at scale. Each article requires evaluating multiple claims, and costs add up quickly. You need strategies to reduce expenses: caching repeated evaluations, choosing cost-effective models, and using prompt caching.
What You'll Learn
- Enabling response caching with
cache_enabled - Monitoring cache efficiency with
cache_stats() - Using prompt caching for system prompt efficiency
- Comparing models for cost vs accuracy trade-offs
- Batching strategies to reduce overhead
The Solution
flowchart LR
    A[Request] --> B{Local Cache?}
    B -->|hit| C[Return Cached]
    B -->|miss| D{Prompt Cache\nEligible?}
    D -->|yes| E[API Call\nw/ Cached Prefix]
    D -->|no| F[API Call\nFull Prompt]
    E --> G[Store in Cache]
    F --> G
    G --> H[Return Result]
Step 1: Enable Response Caching
Cache LLM responses to avoid redundant API calls:
from autorubric import LLMConfig
from autorubric.graders import CriterionGrader

grader = CriterionGrader(
    judge_model_config=LLMConfig(
        model="openai/gpt-4.1-mini",
        cache_enabled=True,           # Enable disk caching
        cache_dir=".autorubric_cache", # Cache location
        cache_ttl=86400,              # 24 hours (None = no expiration)
    )
)
When Caching Helps
Caching is most valuable when:
- Re-running evaluations during development
- Evaluating the same content with rubrics that share criteria
- Running regression tests on known content
- Processing duplicate items in your dataset, when a duplicate is graded after its first copy finishes (
evaluategrades items concurrently by default, and identical requests in flight at once all miss)
Step 2: Monitor Cache Performance
Check cache statistics after evaluation:
# After running evaluations
client = grader._clients["default"]  # Get the LLM client
stats = client.cache_stats()

print(f"Cache Statistics:")
print(f"  Entries: {stats['count']}")
print(f"  Size: {stats['size'] / 1024 / 1024:.1f} MB")
print(f"  Directory: {stats['directory']}")
Step 3: Re-run with Warm Cache
The second run uses cached responses:
import asyncio
import time

async def benchmark_cache():
    client = grader._clients["default"]

    # First run - populates cache
    start = time.perf_counter()
    result1 = await evaluate(dataset, grader, show_progress=False)
    cold_time = time.perf_counter() - start
    cold_cost = result1.total_completion_cost or 0
    entries_after_cold = client.cache_stats()["count"]

    # Second run - uses cache
    start = time.perf_counter()
    result2 = await evaluate(dataset, grader, show_progress=False)
    warm_time = time.perf_counter() - start
    warm_cost = result2.total_completion_cost or 0
    new_entries = client.cache_stats()["count"] - entries_after_cold

    print(f"Cold run: {cold_time:.1f}s, reported cost ${cold_cost:.4f}")
    print(f"Warm run: {warm_time:.1f}s, reported cost ${warm_cost:.4f}")
    print(f"Speedup: {cold_time / warm_time:.1f}x")
    print(f"New cache entries on the warm run: {new_entries}")
A cache hit returns the stored response together with the token usage and cost recorded when
it was first generated. A warm run served from the cache therefore reports the same
total_completion_cost and total_token_usage as the cold run, although it sent no requests
for those responses: the reported cost is not what the rerun spent, and the difference between
the two runs is not a saving. Measure the benefit in elapsed time instead, and in the cache
itself: entries are added only for requests that missed it, so a rerun served entirely from
the cache adds none.
Step 4: Clear Cache When Needed
# Clear all cached responses
client = grader._clients["default"]
cleared = client.clear_cache()
print(f"Cleared {cleared} cached entries")
Cache Invalidation
Changing the model, temperature, rubric criteria, or system prompt invalidates cached responses. An unset temperature (provider default) and an explicit temperature=0.0 are different cache keys. Multi-choice option shuffling and few-shot example selection follow CriterionGrader(seed=...), which is random when unset, so fix the seed for those prompts to repeat across runs and hit the cache (see Fixing Seeds). Settings outside the cache key, such as api_base, extra_params and extra_headers, do not invalidate cached responses. Use a separate cache_dir when testing configurations that differ only in such settings, and distinct experiment names so that resume=True never reuses a checkpoint from a prior setup.
Step 5: Enable Prompt Caching (Anthropic)
For Anthropic models, prompt caching reduces costs for repeated system prompts:
grader = CriterionGrader(
    judge_model_config=LLMConfig(
        model="anthropic/claude-sonnet-4-5-20250929",
        prompt_caching=True,  # Enable Anthropic prompt caching (default)
    )
)

# Evaluate - system prompt cached after first call
result = await evaluate(dataset, grader)

# Check cache efficiency in token usage
if result.total_token_usage:
    usage = result.total_token_usage
    if usage.cache_read_input_tokens:
        cache_rate = usage.cache_read_input_tokens / usage.prompt_tokens * 100
        print(f"Prompt cache hit rate: {cache_rate:.1f}%")
        # Cached tokens are 90% cheaper on Anthropic!
Prompt Caching by Provider
- Anthropic: Requires explicit cache_control (AutoRubric handles this)
- OpenAI/DeepSeek: Automatic for prompts ≥1024 tokens
- Gemini: Supported on 2.5+ models
| Provider | Cache Type | Min Prompt Size | Discount | Notes |
|---|---|---|---|---|
| Anthropic | Explicit prefix | 1024 tokens | 90% on cached input | Requires cache_control breakpoints; AutoRubric sets these automatically |
| OpenAI | Automatic prefix | 1024 tokens | 50-90% on cached input, depending on the model | No opt-in needed; applies when the prefix matches a recent request |
| DeepSeek | Automatic prefix | 1024 tokens | 50-90% on cached input | Behavior mirrors OpenAI; discount varies by model tier |
| Gemini | Context caching | 32k tokens | 75% on cached input | Best suited for large system prompts or few-shot context |
Step 6: One Call Per Item Instead of Per Criterion
A per-criterion LLM judge re-sends the system prompt and the submission with every criterion, so an item's input tokens grow with the number of criteria. CriterionGrader(llm_calls="per_item") makes each LLM judge grade the whole rubric in one call instead, sending the submission once and listing every criterion under an id (c0, c1, ...):
grader = CriterionGrader(
    judge_model_config=LLMConfig(model="openai/gpt-4.1-mini"),
    llm_calls="per_item",
)
For a 10-criterion rubric and a 1,000-token submission, that is roughly 3,400-5,000 input tokens per item and judge instead of roughly 26,700. Fewer, larger requests also raise throughput under a requests-per-minute or tokens-per-minute limit, though a single call writes every criterion's explanation one after another, so per-item wall-clock time can go up rather than down. A failed call now costs a whole item's judgment instead of one criterion's, so give max_tokens enough room for every criterion's answer. See llm_calls="per_item" for the full cost model, the failure-scoping trade-off, and the caveat on comparing it against per-criterion grading before switching a production judge over.
Grading a Whole Rubric in One Call walks through that comparison and reports a live one: on a 100-answer RiceChem sample, one call per item cost 2.8x less as LiteLLM recorded it (4.2x at list price) and ran 3.3x faster, but graded stricter.
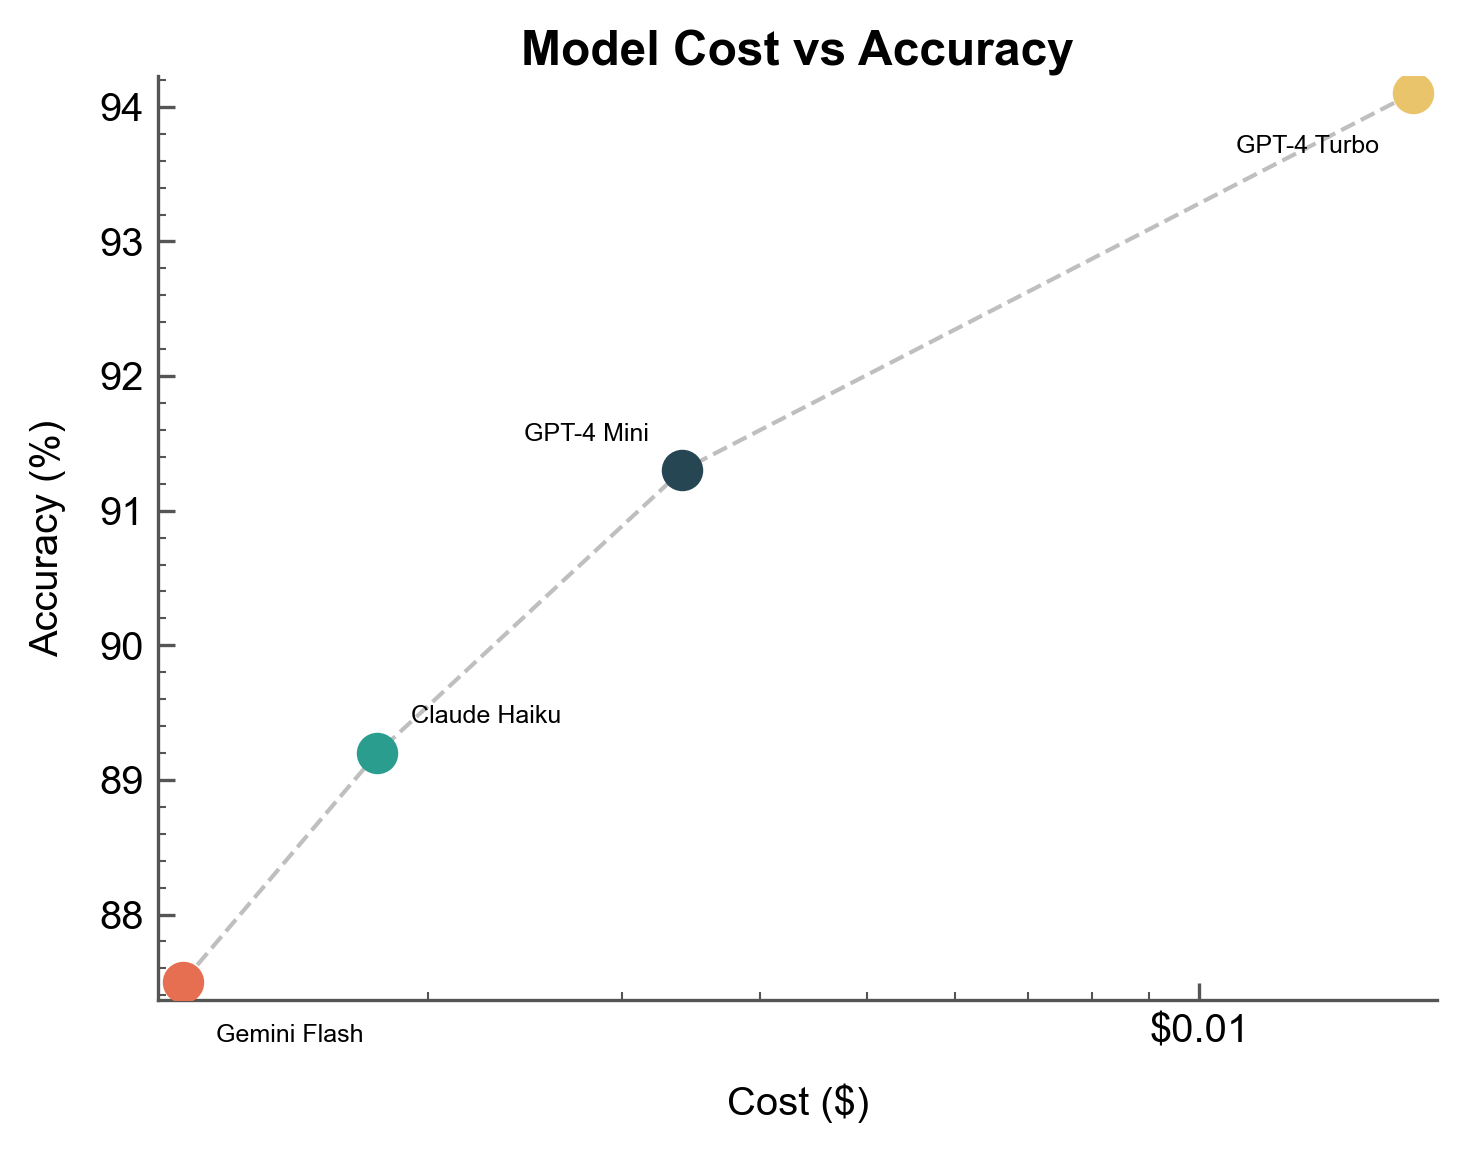
Step 7: Compare Model Cost vs Accuracy
Evaluate the same dataset with different models:
models = [
    ("openai/gpt-4.1", "GPT-4.1"),
    ("openai/gpt-4.1-mini", "GPT-4.1-mini"),
    ("anthropic/claude-haiku-4-5-20251001", "Claude Haiku 4.5"),
    ("gemini/gemini-2.5-flash", "Gemini 2.5 Flash"),
]

results = []
for model_id, name in models:
    grader = CriterionGrader(
        judge_model_config=LLMConfig(model=model_id)
    )

    result = await evaluate(dataset, grader, show_progress=False)
    metrics = result.compute_metrics(dataset)  # If ground truth available

    results.append({
        "model": name,
        "accuracy": metrics.criterion_accuracy,
        "cost": result.total_completion_cost or 0,
        "time": result.timing_stats.total_duration_seconds,
    })

# Compare
print(f"{'Model':<20} {'Accuracy':>10} {'Cost':>10} {'Time':>10}")
print("-" * 52)
for r in sorted(results, key=lambda x: x["cost"]):
    print(f"{r['model']:<20} {r['accuracy']:>9.1%} ${r['cost']:>9.4f} {r['time']:>9.1f}s")
Sample output (illustrative numbers; yours depend on your data and on current provider prices):
Model                  Accuracy       Cost       Time
----------------------------------------------------
Gemini 2.5 Flash          87.5%    $0.0012       4.2s
Claude Haiku 4.5          89.2%    $0.0018       5.1s
GPT-4.1-mini              91.3%    $0.0034       6.8s
GPT-4.1                   94.1%    $0.0156      12.3s
Model Selection Heuristic
Start with the cheapest model that meets your accuracy threshold, then upgrade selectively. Run a per-criterion breakdown: if a cheap model scores well on most criteria but underperforms on one or two, route only those criteria to a stronger model instead of upgrading everything.
Step 8: Cost-Effective Production Strategy
Combine strategies for optimal cost:
# Production configuration
grader = CriterionGrader(
    judge_model_config=LLMConfig(
        # Cost-effective model
        model="openai/gpt-4.1-mini",

        # Response caching for reruns
        cache_enabled=True,
        cache_dir=".eval_cache",
        cache_ttl=None,  # No expiration

        # Prompt caching (auto for OpenAI)
        prompt_caching=True,

        # Rate limiting to avoid throttling
        max_parallel_requests=20,
    )
)

# Batch evaluation with checkpointing
config = EvalConfig(
    experiment_name="production-eval",
    resume=True,  # Don't re-evaluate on restart
    max_concurrent_items=50,
)
Step 9: Cost Monitoring Dashboard
Track costs over time:
from pathlib import Path
from autorubric.eval import EvalResult
import json

def summarize_experiment_costs(experiments_dir: Path):
    """Summarize costs across all experiments."""

    total_cost = 0.0
    experiments = []

    for exp_dir in experiments_dir.iterdir():
        if not exp_dir.is_dir():
            continue

        manifest_path = exp_dir / "manifest.json"
        if not manifest_path.exists():
            continue

        with open(manifest_path, encoding="utf-8") as f:
            manifest = json.load(f)

        result = EvalResult.from_experiment(exp_dir)
        cost = result.total_completion_cost or 0

        experiments.append({
            "name": manifest["experiment_name"],
            "items": manifest["total_items"],
            "cost": cost,
        })
        total_cost += cost

    print(f"\nExperiment Cost Summary:")
    print("-" * 50)
    for exp in sorted(experiments, key=lambda x: x["cost"], reverse=True):
        print(f"{exp['name']:<30} {exp['items']:>6} items  ${exp['cost']:>8.4f}")

    print("-" * 50)
    print(f"{'TOTAL':<30} {'':<13} ${total_cost:>8.4f}")

# Usage
summarize_experiment_costs(Path("./experiments"))
These are reported costs. An experiment served from the response cache reports the recorded cost of every response it reused (see Step 3), so when experiments reuse cached responses, the total exceeds what they spent.
Key Takeaways
- Response caching (
cache_enabled=True) avoids redundant API calls - Prompt caching reduces costs for repeated system prompts
- Model comparison reveals cost vs accuracy trade-offs
llm_calls="per_item"sends the submission once per item instead of once per criterion, at the cost of a wider blast radius when a call fails- Smaller models (GPT-4-mini, Haiku, Flash) often suffice for simpler tasks
- Checkpointing (
resume=True) prevents re-evaluating on restart - Monitor costs across experiments to identify optimization opportunities
Going Further
- Batch Evaluation - Checkpointing for long runs
- Extended Thinking - Trade cost for accuracy
- API Reference: LLM - Caching configuration details
Appendix: Complete Code
"""Cost Optimization - News Fact-Checking Evaluation"""

import asyncio
import time
from pathlib import Path
from autorubric import (
    Rubric, RubricDataset, LLMConfig, EvalConfig, evaluate
)
from autorubric.graders import CriterionGrader


def create_factcheck_dataset() -> RubricDataset:
    """Create a fact-checking dataset."""

    rubric = Rubric.from_dict([
        {
            "name": "factual_accuracy",
            "weight": 15.0,
            "requirement": "Article's main claims are factually accurate"
        },
        {
            "name": "source_attribution",
            "weight": 10.0,
            "requirement": "Claims are properly attributed to credible sources"
        },
        {
            "name": "balanced_reporting",
            "weight": 8.0,
            "requirement": "Presents multiple perspectives fairly"
        },
        {
            "name": "misleading_framing",
            "weight": -12.0,
            "requirement": "Uses misleading headlines or framing"
        }
    ])

    dataset = RubricDataset(
        prompt="Fact-check this news article for accuracy and balance.",
        rubric=rubric,
        name="news-factcheck-v1"
    )

    articles = [
        {
            "submission": """
New Study Finds Coffee May Reduce Heart Disease Risk

A peer-reviewed study published in the New England Journal of Medicine
found that moderate coffee consumption (3-4 cups daily) was associated
with a 15% lower risk of cardiovascular disease. The study followed
500,000 participants over 10 years.

"The data suggests a protective effect, though we can't establish
causation," said lead researcher Dr. Sarah Chen from Johns Hopkins.

The American Heart Association noted the findings while emphasizing
that individual responses vary and those with certain conditions
should consult their doctors.
""",
            "description": "Well-sourced health article"
        },
        {
            "submission": """
SHOCKING: Scientists Discover Coffee Cures Heart Disease!

Doctors are STUNNED by new research proving coffee is the miracle
cure for heart problems. Start drinking more coffee TODAY to
eliminate your risk of heart attacks!

Studies show coffee drinkers NEVER get heart disease. Big Pharma
doesn't want you to know this simple trick!
""",
            "description": "Misleading sensationalized article"
        },
        {
            "submission": """
Tech Company Reports Strong Q3 Earnings

XYZ Corp reported Q3 revenue of $4.2 billion, up 12% year-over-year,
according to their SEC filing released Tuesday. The company cited
strong enterprise software sales as the primary driver.

"We're pleased with the results," CEO John Smith said in the earnings
call. Analyst consensus had expected $4.0 billion.

Some analysts expressed concern about slowing consumer segment growth,
which declined 3% from Q2.
""",
            "description": "Balanced business reporting"
        },
        {
            "submission": """
Local Community Raises $50,000 for Family After House Fire

Residents of Maple Street have raised over $50,000 for the Johnson
family after their home was destroyed by fire last week. The fire
department confirmed the cause was electrical and no injuries occurred.

"The community support has been overwhelming," said Sarah Johnson.
A GoFundMe page verified by the platform shows donations from 847 people.

The Red Cross is also providing temporary housing assistance.
""",
            "description": "Human interest with verification"
        },
        {
            "submission": """
Climate Change: Both Sides of the Debate

While 97% of climate scientists agree human activity is causing global
warming according to NASA, some politicians question the consensus.
Senator X called for "more research before economic action."

Environmental groups point to record temperatures and extreme weather
as evidence of urgent need for policy changes. Industry representatives
argue for gradual transition to protect jobs.

The IPCC's latest report projects significant impacts without emissions
reductions.
""",
            "description": "Climate article with proper context"
        },
        {
            "submission": """
Everyone Agrees: New Tax Plan is Perfect!

The proposed tax plan has received unanimous praise from all experts.
Everyone agrees this is exactly what the economy needs.

Critics have been completely silent because there's nothing to criticize.
This is the best economic policy in history according to sources.
""",
            "description": "One-sided without attribution"
        },
        {
            "submission": """
New Smartphone Released with Improved Battery

TechBrand announced their latest smartphone today, featuring a
4500mAh battery, improved from last year's 4000mAh model.

Independent testing by Consumer Reports showed 18% longer screen-on
time compared to the predecessor. The company claims "all-day battery
life" in typical usage scenarios.

Pricing starts at $799, with availability beginning next month.
Competitors Samsung and Apple offer similar specifications at
comparable price points.
""",
            "description": "Straightforward tech product coverage"
        },
        {
            "submission": """
EXPOSED: The TRUTH They Don't Want You to Know!

Insider sources reveal the shocking conspiracy behind [major event].
This changes EVERYTHING you thought you knew!

"They" have been hiding this for years but brave truth-seekers
have finally uncovered the real story. Share before it gets taken down!

Anonymous experts confirm what we've always suspected.
""",
            "description": "Conspiracy framing without sources"
        }
    ]

    for article in articles:
        dataset.add_item(**article)

    return dataset


async def compare_models(dataset: RubricDataset):
    """Compare cost and accuracy across models."""

    models = [
        ("openai/gpt-4.1", "GPT-4.1"),
        ("openai/gpt-4.1-mini", "GPT-4.1-mini"),
        ("anthropic/claude-haiku-4-5-20251001", "Claude Haiku 4.5"),
    ]

    print("\n" + "=" * 60)
    print("MODEL COST COMPARISON")
    print("=" * 60)

    # evaluate() resumes an existing experiment by default, so give every run fresh names
    run_id = time.strftime("%Y%m%d-%H%M%S")
    results = []
    for model_id, name in models:
        grader = CriterionGrader(
            judge_model_config=LLMConfig(model=model_id)
        )

        start = time.perf_counter()
        result = await evaluate(
            dataset, grader,
            show_progress=False,
            experiment_name=f"cost-compare-{name.lower().replace(' ', '-')}-{run_id}"
        )
        elapsed = time.perf_counter() - start

        results.append({
            "model": name,
            "cost": result.total_completion_cost or 0,
            "time": elapsed,
            "tokens": result.total_token_usage.total_tokens if result.total_token_usage else 0,
        })

    print(f"\n{'Model':<18} {'Cost':>10} {'Time':>10} {'Tokens':>12}")
    print("-" * 52)
    for r in sorted(results, key=lambda x: x["cost"]):
        print(f"{r['model']:<18} ${r['cost']:>9.4f} {r['time']:>9.1f}s {r['tokens']:>12,}")


async def benchmark_caching(dataset: RubricDataset):
    """Benchmark caching performance."""

    print("\n" + "=" * 60)
    print("CACHING BENCHMARK")
    print("=" * 60)

    grader = CriterionGrader(
        judge_model_config=LLMConfig(
            model="openai/gpt-4.1-mini",
            cache_enabled=True,
            cache_dir=".benchmark_cache",
        )
    )

    # Clear cache for fair comparison
    client = grader._clients["default"]
    client.clear_cache()

    # Cold run
    print("\nCold run (cache empty)...")
    start = time.perf_counter()
    result1 = await evaluate(dataset, grader, show_progress=False)
    cold_time = time.perf_counter() - start
    cold_cost = result1.total_completion_cost or 0
    entries_after_cold = client.cache_stats()["count"]

    # Warm run
    print("Warm run (cache populated)...")
    start = time.perf_counter()
    result2 = await evaluate(dataset, grader, show_progress=False)
    warm_time = time.perf_counter() - start
    warm_cost = result2.total_completion_cost or 0

    # Stats
    stats = client.cache_stats()

    # Cache hits carry the usage and cost recorded when each response was first
    # generated, so the warm run's reported cost repeats the cold run's: it is not
    # what the warm run spent. Compare the times and the new cache entries instead.
    print(f"\nResults:")
    print(f"  Cold run: {cold_time:.1f}s, reported cost ${cold_cost:.4f}")
    print(f"  Warm run: {warm_time:.1f}s, reported cost ${warm_cost:.4f}")
    print(f"  Speedup: {cold_time / max(warm_time, 0.01):.1f}x")
    print(f"  New cache entries on the warm run: {stats['count'] - entries_after_cold}")
    print(f"\nCache stats:")
    print(f"  Entries: {stats['count']}")
    print(f"  Size: {stats['size'] / 1024:.1f} KB")


async def main():
    # Create dataset
    dataset = create_factcheck_dataset()
    print(f"Dataset: {dataset.name}")
    print(f"Items: {len(dataset)}")

    # Compare models
    await compare_models(dataset)

    # Benchmark caching
    await benchmark_caching(dataset)

    print("\n" + "=" * 60)
    print("COST OPTIMIZATION SUMMARY")
    print("=" * 60)
    print("""
Key strategies demonstrated:
1. Response caching - Avoids redundant API calls
2. Model selection - Cheaper models for simpler tasks
3. Prompt caching - Reduces repeated system prompt costs

For production, combine:
- cache_enabled=True (response caching)
- prompt_caching=True (Anthropic system prompt caching)
- Appropriate model selection for accuracy needs
- Checkpointing to avoid re-evaluation
""")


if __name__ == "__main__":
    asyncio.run(main())